




Trusted by more than 7M developers
Local AI native to your Apple device.
Run open models, power AI agents, and connect your favourite developer tools you already use - privately on Apple Silicon.
Partnered by
End-to-end infrastructure to build and deploy AI that runs locally on user devices.
Everything you need to build local AI, and everything you need to put it in other people's hands.

Build
Design, test, and ship an AI feature entirely on your own hardware. No cloud call, no API key, no bill.
Deploy
Take what you built off your own Mac and put it to work for your team or your users, without it ever touching the cloud.
Running a model locally is only the beginning. Intelligence needs to fit the device, use memory efficiently, respond fast enough, and work reliably inside a real application.
That is what Neywa builds.
You already own a supercomputer
Our engine is built specifically for Apple Silicon
It means it runs locally on your machine, free and offline.
It powers products built by us and other companies.

Run AI on your Mac
Run models locally, connect agents, developer tools and apps through standard APIs - no per-token bills, no shipping your data to someone else's cloud.
Trusted by more than 7M developers
Build AI products that run locally
Build applications that can read, see, hear, speak, and create directly on personal hardware.
Our omni engine brings together our work across multimodal model support, inference, quantization, memory optimization, and device-aware performance.
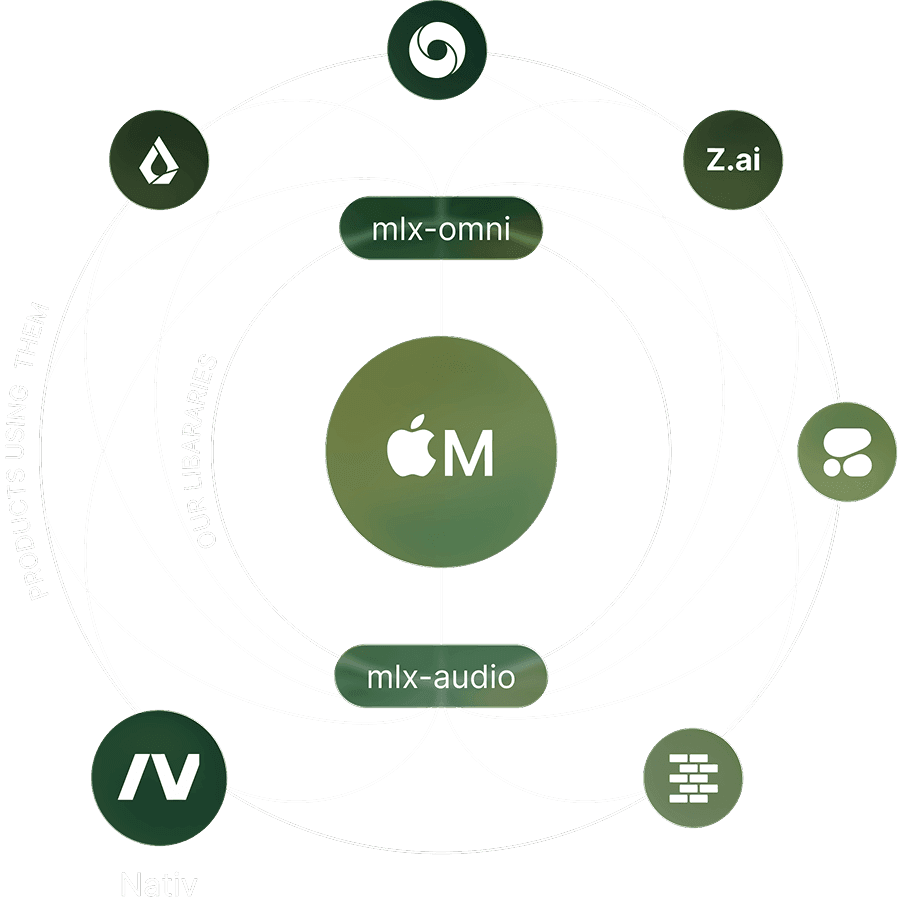
Bring your model on-device.
We work with model labs to turn new architectures into efficient, usable on-device implementations.
Our work can include:
Architecture implementation and model bring-up
Quantization and memory optimization
Vision, audio, video, and multimodal inference
Apple silicon and MLX support
Performance validation across devices
Reference applications and developer examples
Model releases prepared for local adoption
Day-one support for new model launches
The result is more than a successful inference test. It is a model developers can understand, evaluate, and build into products.
Developers from across the world build on us
Sinan
AI video creator
Istanbul, Turkey
MLX-VLM
“Switching to Apple Silicon completely changed how we handle video pipeline at Sinners, and MLX-VLM quickly became core to our stack. It gives us the efficiency to run local video analysis and frame-by-frame scene continuity tracking without relying on cloud APIs. We initially tested it with smaller Qwen models, scaled across different LLMs, and it’s been a permanent part of our workflow ever since.”
Daryl
Entrepreneur
Honolulu, Hawaiʻi
MLX-VLM
“I build offline AI tools for our community in Hawaii, where we experience regular power and internet outages during severe weather. Research into comparing inference engines on Apple Silicon led me to the MLX framework, and I found the speed up from using MLX-VLM to be the most promising development towards building on-device applications to increase the resilience and security of our community.”
Nativ
“What stood out to me about Nativ was how it makes local AI easier to navigate. Its model library helps you discover the right model for each use case instead of leaving you to figure everything out on your own. For professionals handling privileged, confidential or commercially sensitive information, keeping sensitive workflows local can be extremely valuable. In my view, a hybrid setup (local AI alongside frontier models) offers a strong balance between privacy and capability.”
Bring the datacenter
to your desk
You already have a supercomputer. Run it locally, in the open